AI Engineering · AI FinOps
Tokens got cheaper. Your AI bill didn’t.
Per-token prices have dropped sharply since 2023, yet most teams pay more for AI every quarter. When something gets cheaper, you use a lot more of it.
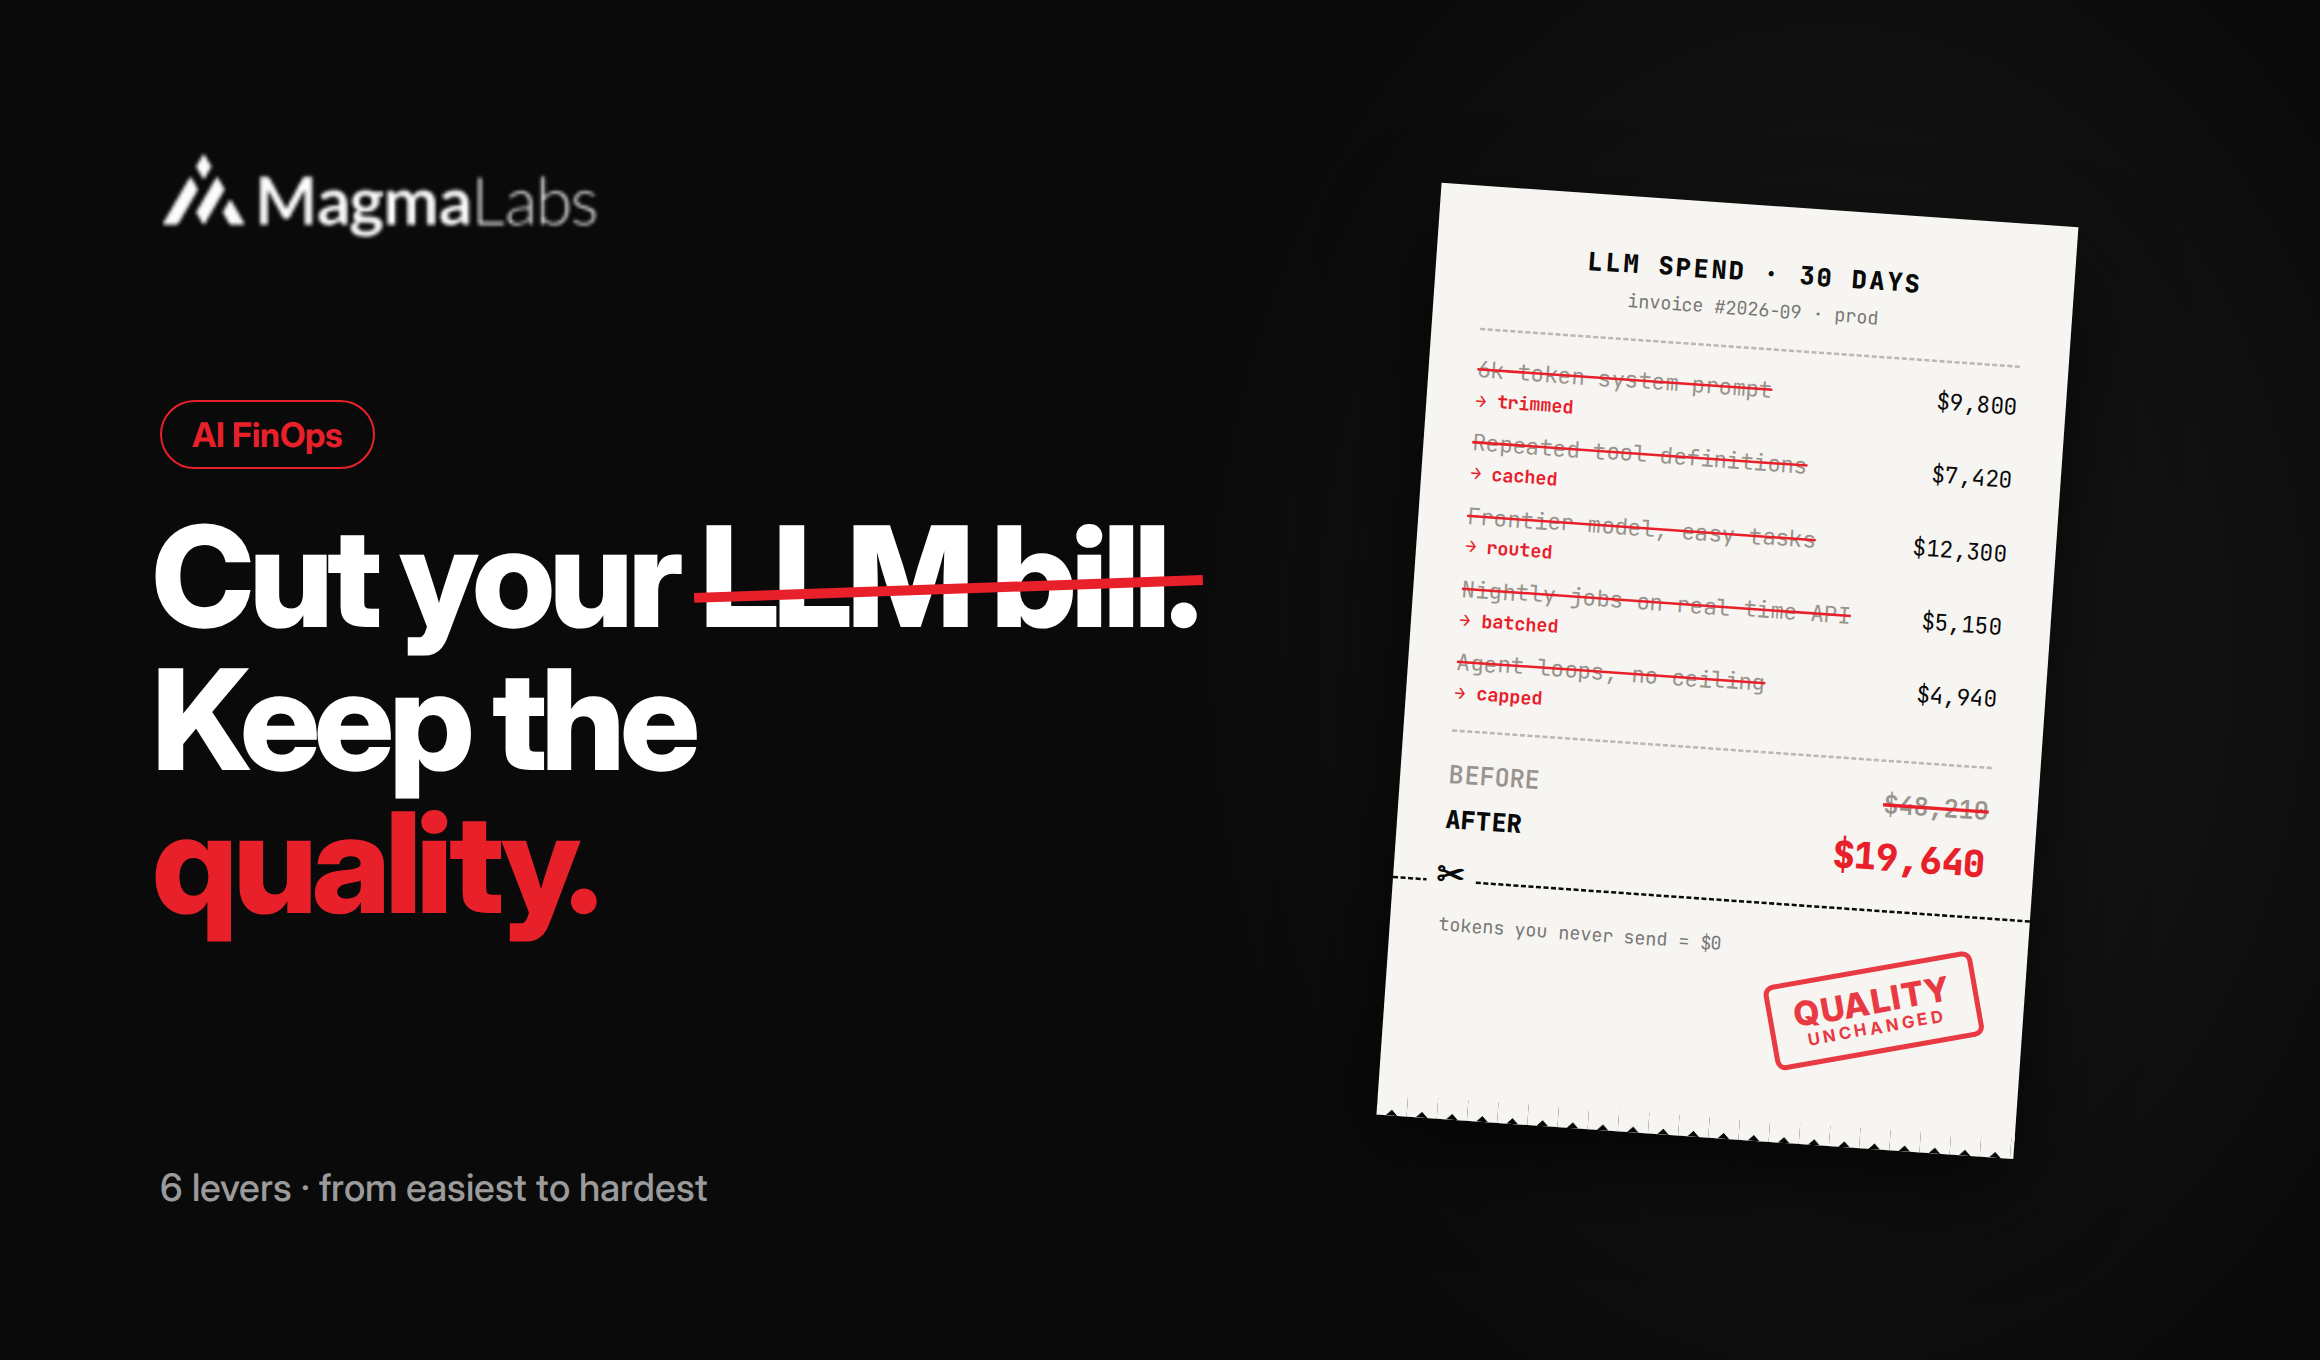
Agents call models in loops, prompts grow every sprint, and nobody can say which feature is burning the budget. This is a practical guide to LLM cost optimization: six levers, from easiest to hardest, that cut spend without making your product dumber.
📌 TL;DR — The Short Answer
To cut LLM costs without losing quality, measure cost per successful outcome first, then trim context, cache repeated prompts, route easy requests to smaller models, batch work that can wait, and cap agent loops. Most savings come from sending fewer tokens, not from buying cheaper ones. That discipline is called AI FinOps.
Why are LLM costs rising if tokens are cheaper?
Because usage scales faster than prices fall. The State of FinOps 2026 puts the vast majority of AI spend in inference, the part that grows every time a user clicks. And one user action rarely means one call: an agent plans, calls tools, retries, and re-reads its history on every step.
Three patterns show up in almost every bill we audit: bloated system prompts, a frontier model answering questions a small model could handle, and agents with no ceiling on how long they loop. We covered that last one in 7 production mistakes to avoid.
Short answer
AI FinOps is the practice of tracking, attributing, and optimizing what you spend on models, tokens, and inference so every dollar ties back to a business outcome. It borrows the accountability of cloud FinOps, but measures cost per answer instead of cost per server.
6 levers to cut your LLM bill, from easiest to hardest
Measure cost per successful outcome
Divide spend by successful outcomes: a resolved ticket, an accepted draft. A cheap call that fails and escalates to a human isn’t cheap.
Start here: add feature and tenant_id to your LLM logs. It takes an afternoon.
Put your prompts on a diet
Start here: log average input tokens per call. That’s your baseline, and every token you cut is saved on every call.
Cache what repeats
Start here: turn on prompt caching for long system prompts. For FAQ traffic, add a semantic cache that skips the model entirely.
Route by difficulty, not by habit
The RouteLLM research showed routing can cut costs by more than half on some benchmarks while keeping most of the stronger model’s quality.
Guardrail: gate every routing change on your eval suite. No evals, no routing.
Batch everything that can wait
Start here: list every job where nobody is waiting for the answer. That list is your fastest 50%.
Cap the loops
Start here: set a per-run ceiling and a fallback, as we explain in How to Build an AI Agent That Is Actually Production-Ready.
The cheapest token is the one you never send.
Which lever should you pull first?
| Lever | Effort | Best for | Risk to quality |
|---|---|---|---|
| Cost attribution | Low | Every team, day one | None |
| Prompt diet | Low | Long prompts, RAG | Low, if tested |
| Caching | Medium | Repeated context, FAQs | Very low |
| Model routing | High | Mixed easy and hard traffic | Medium without evals |
| Batching | Low | Async, back-office jobs | None |
| Loop budgets | Medium | Agents in production | Low, with fallbacks |
Our rule of thumb: attribution and batching first, because they’re nearly free. Routing last, because it’s the only lever that can quietly hurt quality.
Is your AI bill growing faster than your AI results?
15 years shipping software, now building AI features inside real product teams, with evals, guardrails, and cost budgets from day one. Share your setup and we’ll show you where the tokens are going.
Frequently asked questions
What is AI FinOps?
AI FinOps is the discipline of tracking and optimizing spend on AI models, tokens, and inference so it ties back to measurable business value. It extends cloud FinOps with AI-specific metrics like cost per token, cost per request, and cost per successful outcome.
How can I reduce LLM costs without losing quality?
Send fewer tokens before you look for cheaper ones. Trim prompts, cache repeated context, batch non-urgent work, and cap agent loops. Route requests to smaller models only after you have an evaluation suite that proves quality holds.
Is prompt caching worth it?
Usually, yes. If your calls share a long system prompt, tool definitions, or reference documents, caching bills those repeated tokens at a reduced rate and also lowers latency. It’s one of the lowest-risk optimizations available.
What metric should I report to finance?
Cost per successful outcome. Spend per API call hides failures and retries; cost per resolved ticket, accepted draft, or completed task shows whether AI is actually cheaper than the process it replaced.
About MagmaLabs — Nearshore product engineering. 15 years, 200+ shipped projects across HealthTech, FinTech, eCommerce, and Mobility. See how we build AI.